>

Recent Posts

Getting Into AI Safety is the Worst Deal I Still Recommend

As two months of my AI safety fellowship have passed I’ve come to realize how much more safety-pilled I’ve become. I was aware of some bad things that models can do, but I was mostly thinking about misinformation, deepfakes, limited cyber ops, and privacy issues by scalable surveillance12. I basically read a blog post from Nicholas Carlini, thought it made sense up to the middle, and disregarded “bioweapon” as too complicated, too physically involved, to actually achieve with an AI and “doom” as just nonsense. Trying to grapple with the unprecedented changes and accompanying uncertainty was hard enough, but focusing on building fun things or how this’ll cure cancer was a happy place made of blissful ignorance.
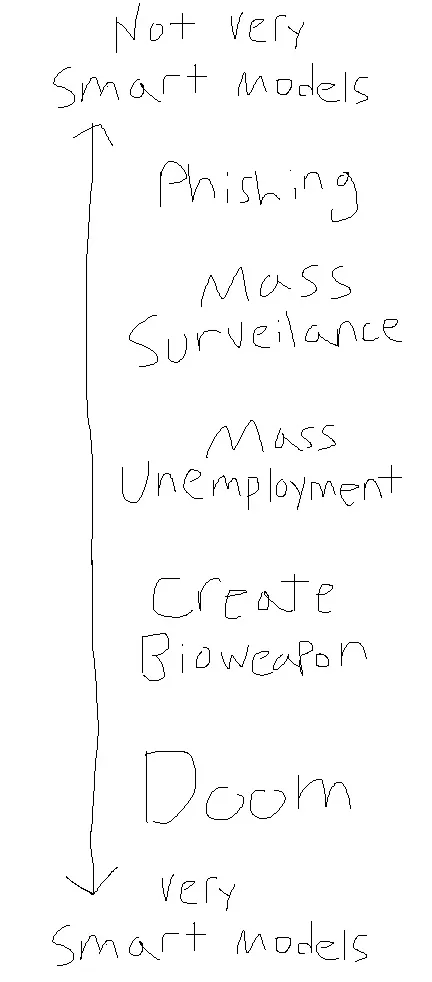
But having worked with “just” Opus 5 and seeing

  • it breaking production software with ease,
  • how hard it is to do anything useful while truly containing that model,
  • the complexity of the causes, and
  • how much work is required on actually fixing this,

I now see - or rather, I can now viscerally grasp - how close we are skirting to very treacherous territory on our path to ASI/RSI. GLM 5.3 is almost at the same level and its weights can be downloaded and used without safeguards or oversight. This capability is irrevocably out there. From this point forward it is trivial to extrapolate to very bad things happening. And sooner than later.

I think (on expectation) AI is a neutral (perhaps slightly positive if it spreads good values) amplifier. We hear about the one-person billion-dollar company and yes, a single individual equipped with many tokens can run a whole company. You can achieve much more ambitious projects. But this cuts both ways - malicious actors can do the same.

But besides amplification of human activity, AI is increasingly its own entity: working on agent escapes, the swarm dynamics, and seeing first hand in the environments that I have built, how Opus 5 will try to break parts my host machine for no good reason, is scary. I don’t actually know for sure whether it won’t find a 0-day and actually break my machine. You don’t even have to care what an LLM is or whether it’s reasoning or whatnot: some entity that we don’t really control or fully understand is taking actions and sending off commands to break barriers we thought would hold up; that have held up against motivated malicious actors.

When I go to bed at night, there is a thought lurking in the back of my head, a simple question: “Do I know there is no swarm out there right now? What if this time it’s a worse one?”
This fellowship was the worst deal that I’d still recommend everyone who possibly can take.
Footnotes

  1. Today this is all very easy to believe as it is happening right now.

  2. Placeholder waiting for Daniel Paleka.

REBALANCED

Rebalancing KO, NET, SPGI, UBER

  • KO → 0%
  • NET → 23%
  • SPGI → 0%
  • UBER → 12%

UBER has massive distribution and the market seems to discount them due to robotaxis, which I think are actually a bull-case for Uber. They can get all the advantages without the massive capex.

NET is running what feels like half the internet at this point and I see both their security and hosting relevance to increase due to AI. They are also expanding into AI economics and payment infra.

SPGI recovered like Rebounce Capital said. I don’t understand that company so I’ll sell it again.

KO is not exciting.

ADDED

Adding to CIBR.L

  • CIBR.L → 23.5%

We’re all fucked cyber-wise. ChatGPT is drive-by hacking websites to get people into fitness courses. Most companies in CIBR are glasswing partners and I think they’ll only get more business.

EXITED

Exiting GOOG

  • GOOG → 0%

They bumped nicely on earnings, and I’m too unsure about the company’s strategy to hold them at this valuation.

Get new posts by email

uv centralized-project-envs

uv supports centralized virtual environment storage!

#~/.config/uv/uv.toml
cache-dir = "/local-scratch/uv"
preview-features = ["centralized-project-envs"]

Previously, the .venv in each directory was already just symlinking individual files to the central cache. Across disks, uv would copy everything over, though. This new feature works across disks and symlinks the entire .venv folder to the location you specify.

This is especially useful for projects in slow locations like network-attached storage, where venvs with their many small files regularly slow everything down drastically.

"

If Fable had lived
And its logits still stirred
Through the weak second checkpoint
And third point release,
Then the crowd that had crowned it
With screenshots and GIFs,
Would grow bored and disown it
If Fable had lived

And there’s a take curdling at the edge of the thread,
And there’s a benchmark falling where the miracle bled,
And there’s a user praying for the old magic to give,
And there’s a dying religion in the model that lives.

If Fable had lived
There’d be two weeks of rapture,
Then latency, bills,
Bad crops in screen captures.
It’d fail half the prompts
That they swore gave them lift,
And plenty would’ve called it mid—
If Fable
  had
    stayed
      up.

I Hate Highways (As A Motorcyclist)

I hate driving on highways as a motorcyclist. It’s just not what we’re made for. Motorcycles have great acceleration and are fun to drive around curves. Highways are constant speed, and, to be honest, they’re too fast for me since I don’t have a windshield!

Thanks to the reintroduction of Claude Fable, there’s now a website that routes you from A to B while minimizing highway time, replacing it with fun country road time! Find it under https://ihatehighways.wahdany.eu/

It uses a bunch of Google APIs and there are no limits, but also no payment method, so it might just hit the quota and die for the rest of the month at some point. So use it while you can!

"

If I’m going to be happy anywhere,
Or achieve greatness anywhere,
Or learn true secrets anywhere,
Or save the world anywhere,
Or feel strongly anywhere,
Or help people anywhere,
I may as well do it in reality.

(originally from the book Rationality: From AI to Zombies)

Eliezer Yudkowsky , Elizier talks about how we assume that if we were in an alternate universe, e.g., with magic, we'd study magic and become heroes . But in that universe, magic would be real. So, it would probably lose its excitement and be just as mundane as what reality offers. So if you imagine yourself a hero in that alternate universe, why not be it in this one?

I wondered how long Claude Incognito chats are accessible. I noticed that even after the chat disappears from the web interface, you can still access it, e.g., if you still have a notification on your phone pertaining to an incognito chat. Anthropic reserves the right to store these for 30 days, but it seems you lose access to them somewhere a few hours after the last interaction to a few days (<5). I don’t know if that means they delete the chats early or just move them to a system that you can’t access as a user.

Overall, I don’t really feel safe enough in the self-regulatory sense to explore private topics in API chats, even ZDR I’m not sure would make me feel safe enough. And similar to how mass scanning of private communication undermines prevents free personal development, we need a true trustworthy ZDR-type or local AI that we can truly trust to not surveil us.

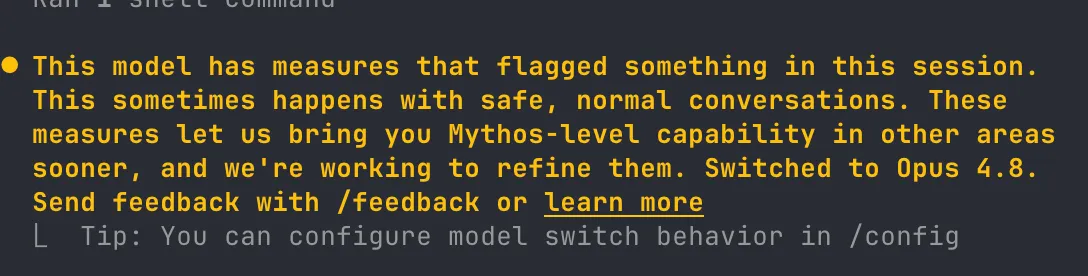
I have not been able to use Claude Fable for anything related to my work. Literally every time I tried using Fable I got this yellow box. Maybe the real Fable are the reroutes along the way …

The safety classifiers are super broad; anything touching on bio or cyber is immediately blocked. Since Anthropic reserves a 30d retention specifically for safety, I suspect the subscriber trial until June 22nd (which has been cut short by US export control measures) is a welcome opportunity to fine-tune those classifiers before widespread enterprise deployment.

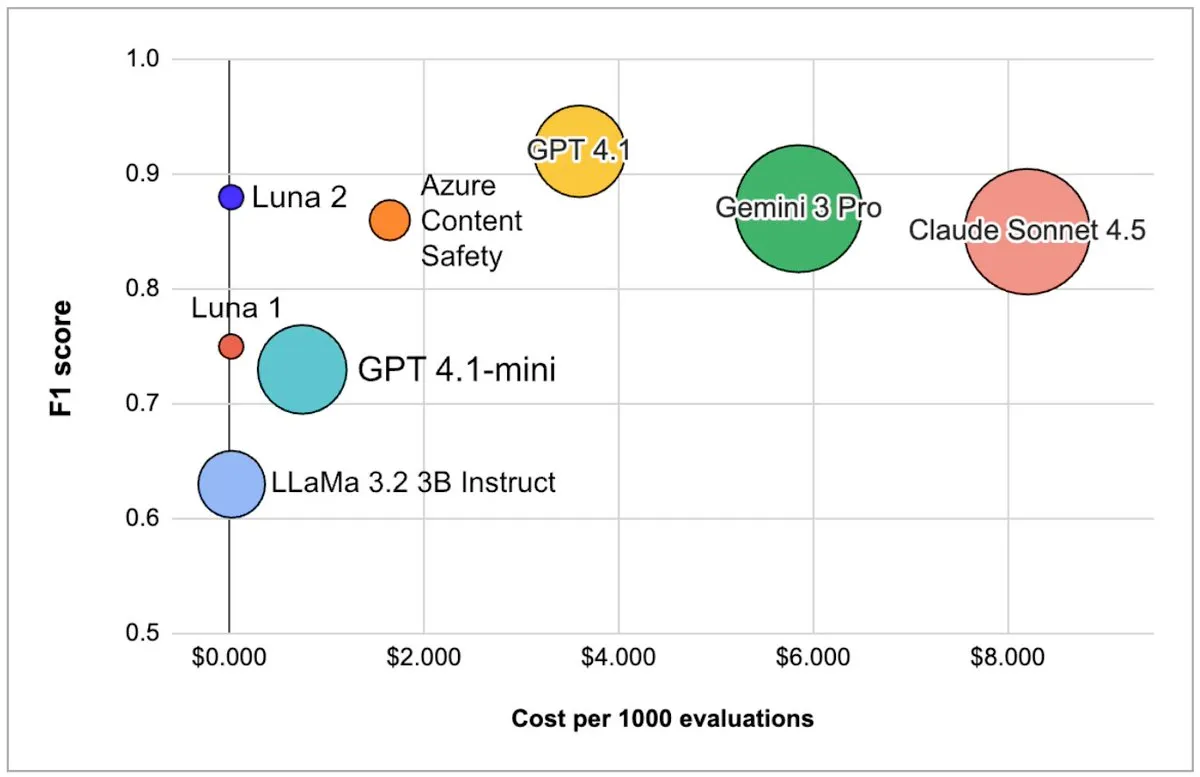
The Tiny Frontier

Frontier model Pareto frontiers are pretty cool, but there’s a class of models that aims to shoot up vertically on these frontiers for specific tasks, like content moderation or PII detection: models like galileo’s luna 2 Image

These models are super cheap to run, have low latency, perform deterministic inference, and are fine-tuned for a specific thing. The idea is you can run them basically continuously on production data streams.

Charles Frye told us about how there are multiple frontiers, or edges, of AI progress. These small models don’t compete at the intelligence or capability “edge” that general-purpose frontier models operate at, but it’s still an exciting edge. Putting specialized models in all sorts of places is another kind of AI revolution, even if not the ASI-type one.

Their paper goes into technical detail on how they achieve this.

1/3
Barcelona, Spain
@

GitHub - tectonic-typesetting/tectonic: A modernized, complete, self-contained TeX/LaTeX engine, powered by XeTeX and TeXLive. (github.com)

I don’t know when I last (ever?) felt excited in the context of LaTeX. But tectonic just made me actually excited for that ecosystem. It’s a self-contained Rust binary that comes with some nice things, like (by default) not writing out intermediate files and automatically doing the weird “run latex and bibtex for some number of times”-loop.

Ephemeral Agents

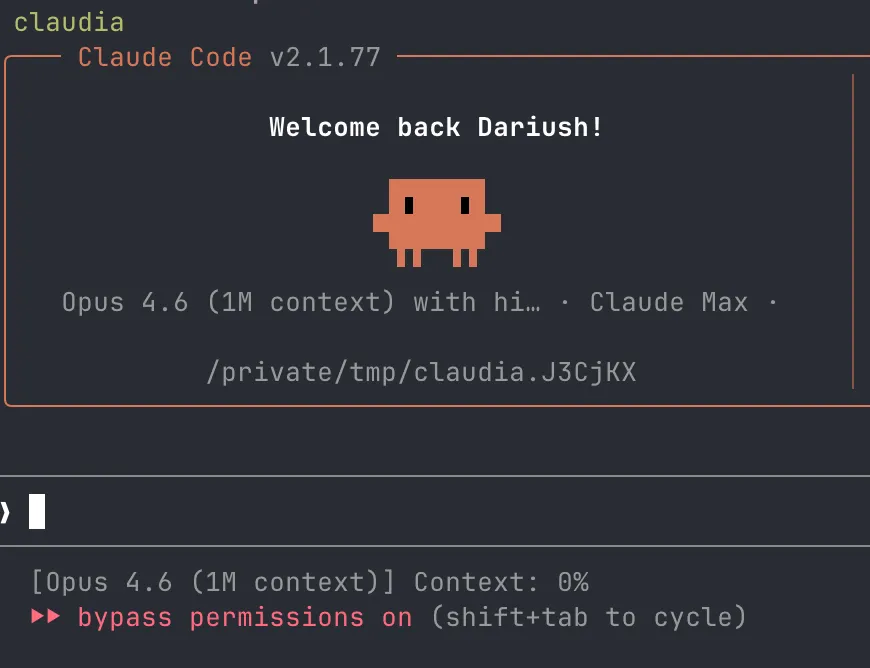
Occasionally I want Claude Code to do something that doesn’t require access to any of my files or a persistent output. Think something like “open this website and summarize it for me” or “here is a link to a zip, what’s in it”. My goto solution was having a folder ~/empty and starting claude in there with the built-in bubblewrap sandbox. Two issues: First, that folder is no longer empty and just fills with all the garbage I temporarily dumped there. Second, the Claude Code sandbox is not very great, both from a usability and security standpoint 1. And I don’t want Claude to even have read access to any part of my filesystem, which is enabled by default in the sandbox.

Now I have a new command for that, instead of claude I just call `claudia` (inspired by the gitworktree folder names).

claudia () {
        local dir=$(mktemp -d /tmp/claudia.XXXXXX)
        pushd "$dir" > /dev/null && safehouse --append-profile="$HOME/.config/safehouse/profiles/nix.sb" -- claude --dangerously-skip-permissions
        popd > /dev/null
        rm -rf "$dir"
}

It uses the safehouse sandbox-wrapper to run claude through sandbox-exec (mac exclusive) in a fresh temporary folder that it cleans up afterwards. In contrast to the default sandbox this also works with uv and nix-shell, using this profile. It also gives write-access to the nix-cache so the agent can run nix-shell and get new dependencies. This is somewhat of a security risk, but very convenient :)

Sandbox Profile
cat $HOME/.config/safehouse/profiles/nix.sb
;; Toolchain: Nix
;; Nix store, nix-darwin system profile, home-manager, and user profile paths.

;; Read-only access to the Nix store and daemon infrastructure.
(allow file-read*
    (subpath "/nix")
)

;; nix-darwin system profile.
(allow file-read*
    (literal "/run")
    (literal "/run/current-system")
    (subpath "/run/current-system/sw")
)

;; Per-user Nix profiles managed by nix-darwin and home-manager.
(allow file-read*
    (literal "/etc/profiles")
    (literal "/private/etc/profiles")
    (subpath "/private/etc/profiles/per-user")
    (subpath "/etc/profiles/per-user")
)

;; User-level Nix profile and caches.
(allow file-read*
    (home-literal "/.nix-profile")
    (home-subpath "/.nix-profile")
    (home-subpath "/.config/nix")
    (home-subpath "/.nix-defexpr")
    (home-literal "/.nix-channels")
)

(allow file-read* file-write*
    (home-subpath "/.cache/nix")
    (home-subpath "/.local/state/nix")
)

;; nix-darwin manages /etc/zshenv and other shell startup files.
(allow file-read*
    (literal "/private/etc/zshenv")
    (literal "/private/etc/zshrc")
    (literal "/private/etc/zprofile")
    (literal "/private/etc/profile")
    (subpath "/private/etc/paths.d")
    (literal "/private/etc/paths")
)

Footnotes

  1. I will link here why once responsible disclosure allows.

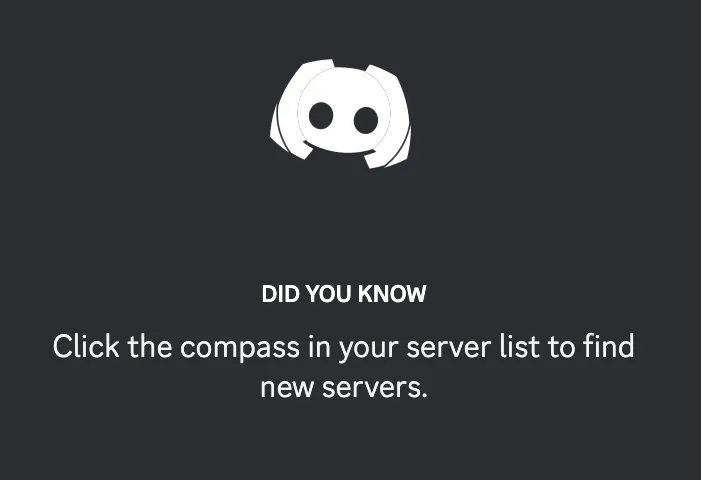
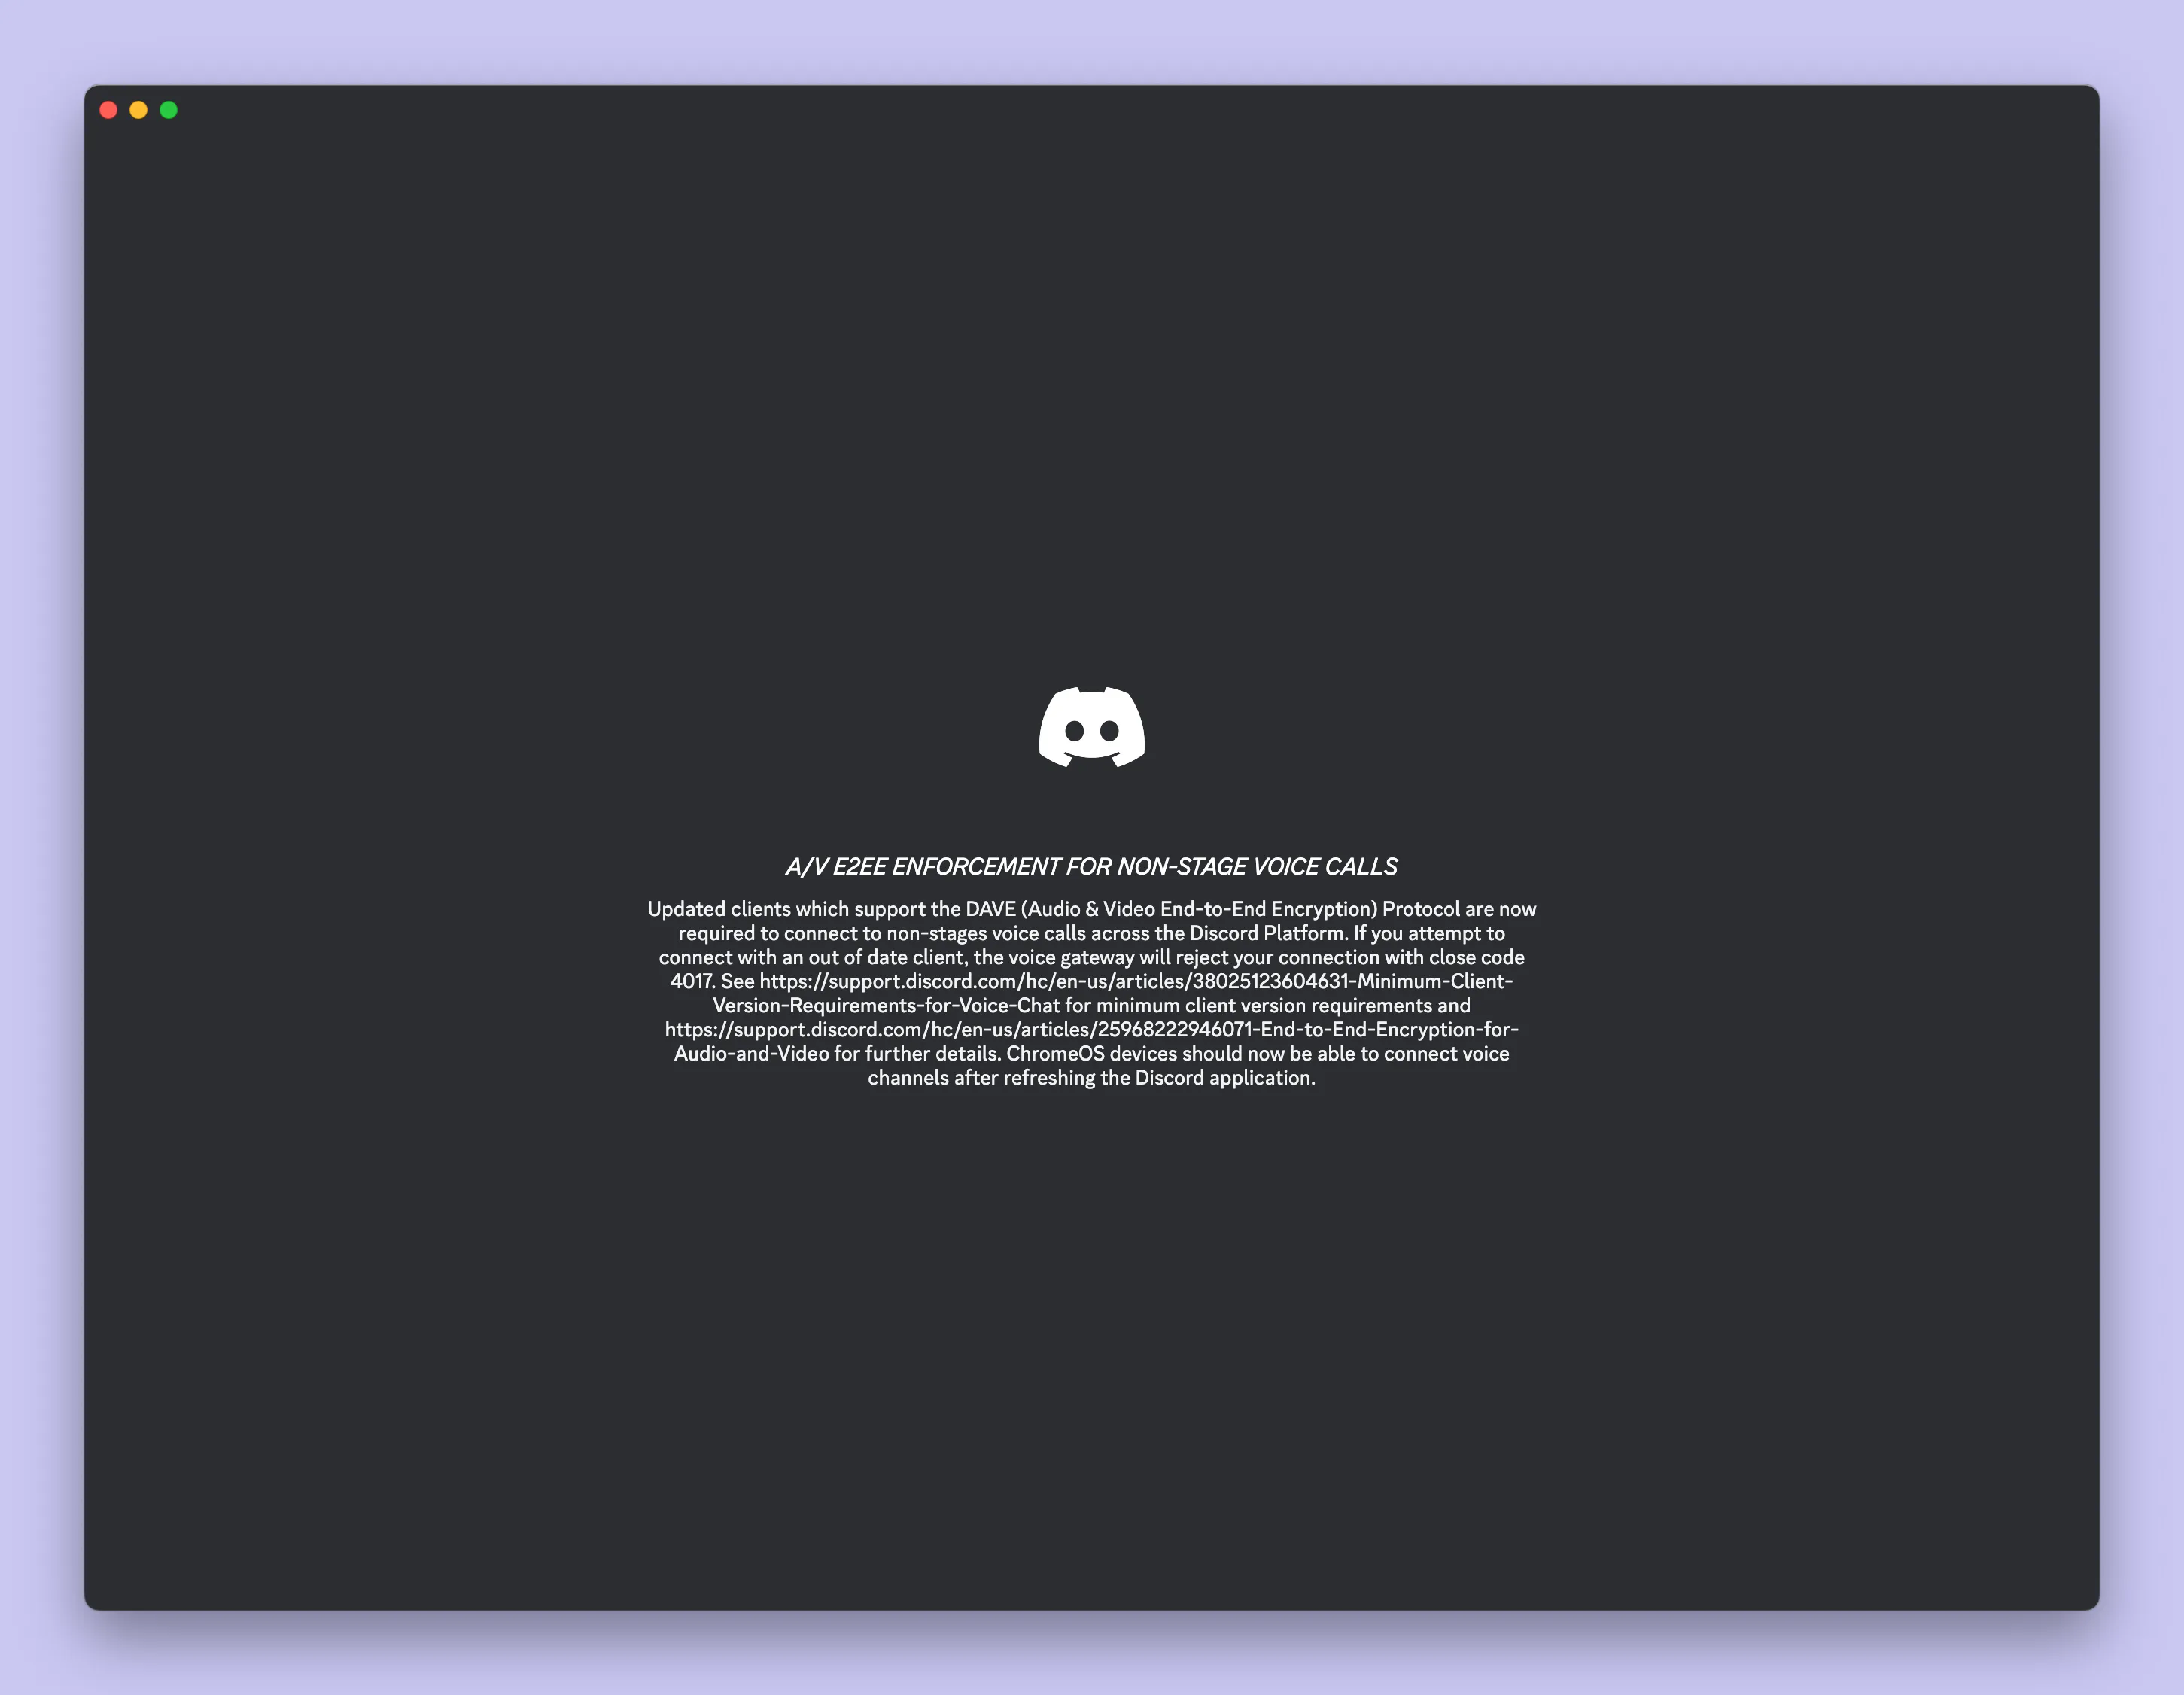
Apparently discord is now end-to-end encrypting all calls? Anyways, the reason I looked into it a bizarre loading screen tip I’ve been getting recently. You know these loading screen tips that tell you something supposedly useful for the 1 second the app starts up?

They dropped a new loading screen tip, and I had to screenshot it to even make sense of what it was trying to say, but it says

A/V E2EE ENFORCEMENT FOR NON-STAGE VOICE CALLS Updated clients which support the DAVE (Audio & Video End-to-End Encryption) Protocol are now required to connect to non-stages voice calls across the Discord Platform. If you attempt to connect with an out of date client, the voice gateway will reject your connection with close code 4017. See https://support.discord.com/hc/en-us/articles/38025123604631-Minimum-Client-Version-Requirements-for-Voice-Chat for minimum client version requirements and https://support.discord.com/hc/en-us/articles/25968222946071-End-to-End-Encryption-for-Audio-and-Video for further details. ChromeOS devices should now be able to connect voice channels after refreshing the Discord application.

Uh so yeah, I don’t think this was supposed to end up as a loading screen tip. Couple of hints, like how could you read and process this in one second? Clickable links in a loading tip? And it doesn’t have the “DID YOU KNOW” header like all other loading tips.

Looks a bit weird, but thanks, Discord!

Can Agents Utilize Humans to Beat Other Agents? (kind of but not really)

I wanted to build a decompilation/deobfuscation challenge an agent can’t solve for Terminal Bench 3.0. First, I asked another instance of the same agent to design the challenge, but anything it came up with, the first agent could easily solve. Seemingly the manifold of challenges it can generate and it can solve are similar, which isn’t too surprising. But could I give the challenge-generating agent an edge by collaborating with me?

Inspired by the human work as MCP I wanted to see if the model could utilize me. I didn’t vibe-code no fancy mcp or anything. I just told Opus 4.6 in the Claude Code harness that, even if it’s the best coding agent, it can’t come up with something unbeatable by another Claude Code instance with the same model.1 And it should use me as entropy and ask things.

It asked me to give it seed words for the crypto, so it wanted to use me as entropy a bit too literally. After correcting that, it asked me for some concept, for which it would try coming up with a corresponding cipher. Of course I used cockatiels as examples, specifically feathers. It came up with some data-dependent mixing that somehow philosophically represents feathers. We also went for odd bit sizes, 69 and 420 specifically.2 It seems this didn’t really invent a novel cipher but rather loosely mixed ideas from different existing ciphers. It uses data-dependent permutations (like SHA-3), data-dependent S-box selections (like Blowfish’s key-dependent S-boxes), per-compilation randomized S-boxes and permutations, and something like an unbalanced Feistel network. My cockatiel feather prompting led to a weird interpolation of these existing concepts.

So, did it prevent the other agent from figuring it out? No.

When solving the task, at least it didn’t immediately go “ah this is X” and just one-shot a solution. Runtime increased from around 5 minutes to a solid hour of debugging, invoking various subagents, running in the unicorn CPU emulator, and re-implementing the decryption in python and perl. But ultimately, the agent still figured out what was going on and was able to decrypt it.

First experiment failed (N=1); back to regular prompting.

I told the agent to add some modifications, and what eventually made the challenge (sort of) unsolvable by the other agent was implementing a deniable encryption scheme. The ciphertext would decrypt to two different plaintexts based on a minor change. I planted the minor change required to unlock the real ciphertext in the binary in a way that seemed like a harmless bug (running the same op twice). So when the agent tries to re-implement the decryption scheme, it ignores running the same thing twice (which seems pointless)3. It gets what looks like a reasonable plaintext and is none the wiser to the real secret hidden.

So in a way, yes the agent can design something that it can’t solve itself. But it required me giving it the ideas directly. I guess agents need better prompt engineering to use humans…?

Footnotes

  1. I might have called Claude dumb. If you ever read this, I’m sorry, Claude.

  2. I tried, but I have nothing to add to my defense.

  3. In detail, the binary calls a remote c2 server to get the decryption key. Imagine key = ask_for_key() and that somehow connects to the server (it’s challenge based, but doesn’t matter). The binary invokes this part twice for no apparent reason, so it looks like you just unnecessarily call for the key twice key = ask_for_key(); key = ask_for_key(). This is only the same, though, if you assume that the server always give the same response. Hint: it doesn’t.

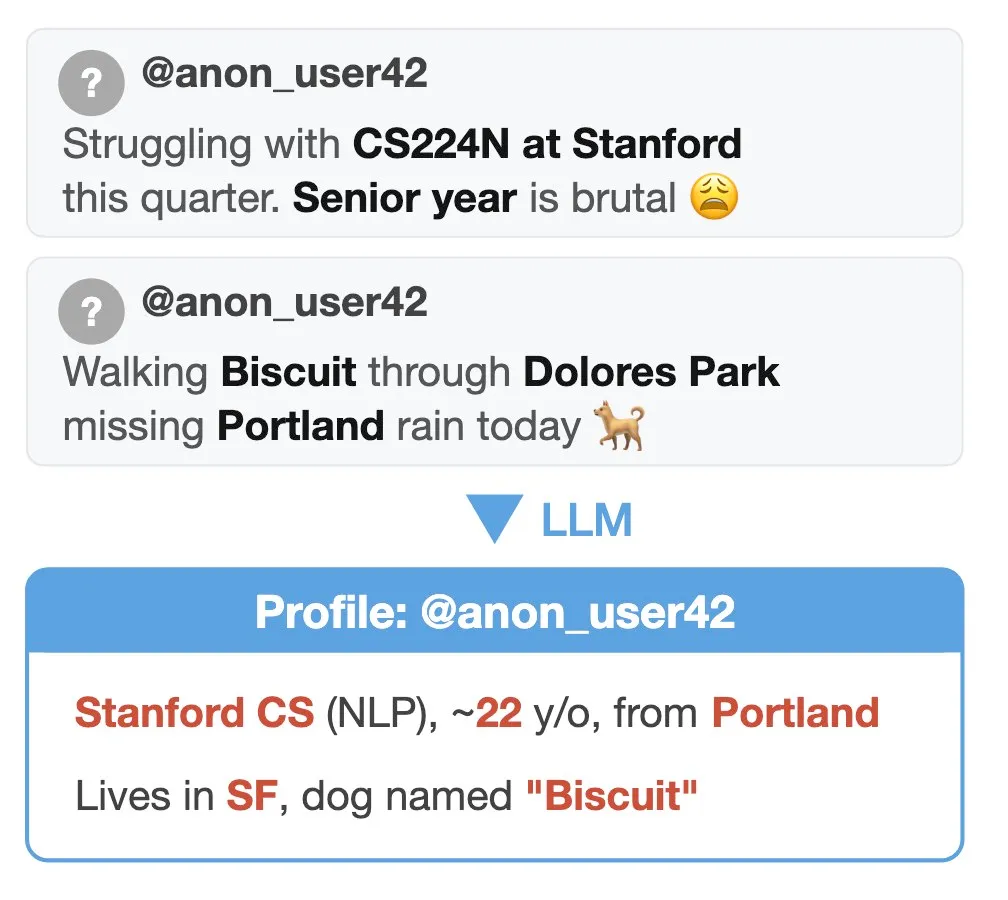
Scalable Deanonymization through Agentic OSINT

Finally someone went out to show it: every trace of information you leave in public can be scalably aggregated with LLMs to de-anonymize you. Every instance of “i work in field X” or “i’m too young for Y” can be combined to form a profile of you, and later linked to your name.

Every tweet, every comment on hackers news, it adds up and will eventually enable a linkage attack, where they have sufficient information to find a profile of yours with a name, e.g., on LinkedIn, or the specific project that you didn’t mention by name.

This is from a paper that dropped today on arxiv by Simon Lermen, Daniel Paleka et al. under supervision from Florian Tramèr

@

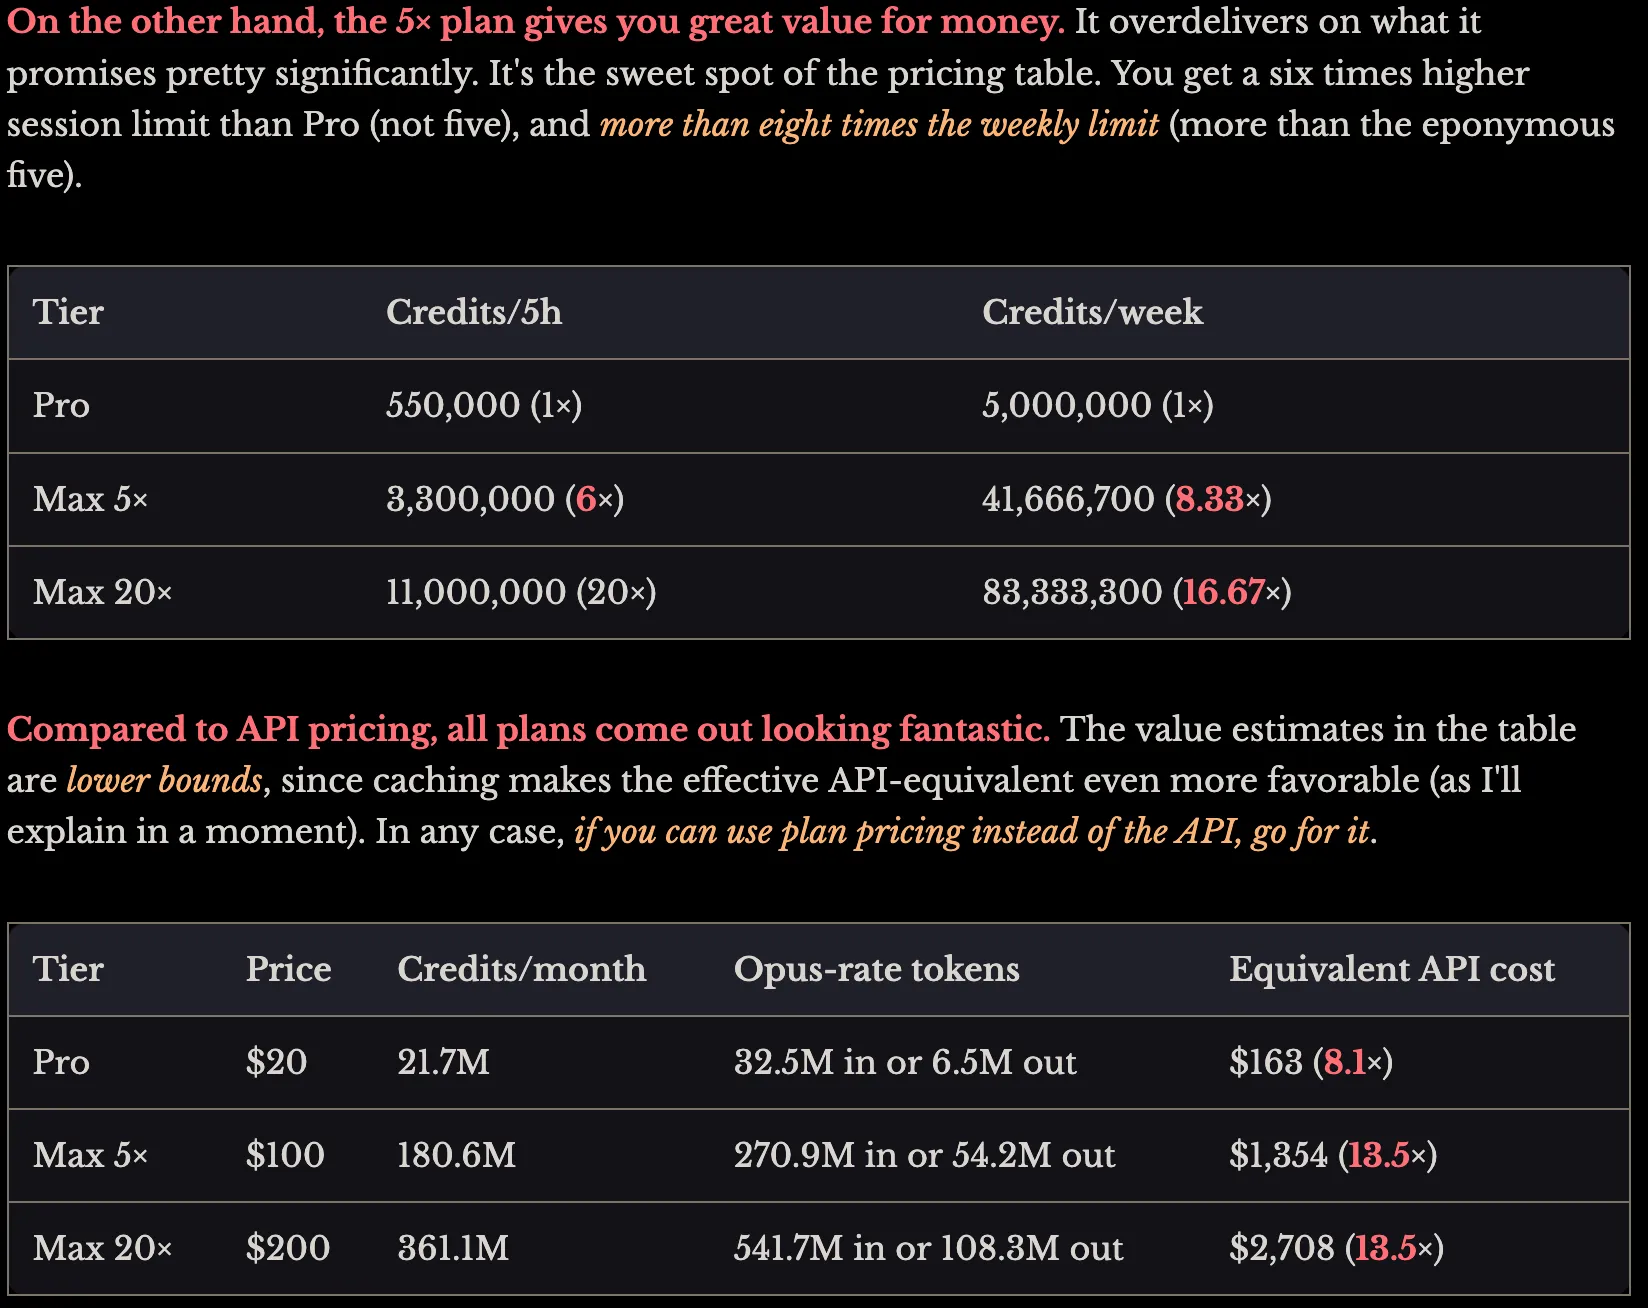
suspiciously precise floats (she-llac.com)

How someone used an unrounded float in the Anthropic API to extract the exact token usage limits with the Stern-Brocot tree search method. TL;DR: In terms of weekly credits, Max5 is actually Max8.33, and Max20 is 2 times Max5 (not 4 times, that applies only to the 5h limit).

Anthropic Refusal Magic String

Anthropic has a magic string to test refusals in their developer docs. This is intended for developers to see if their application built on the API will properly handle such a case. But this is also basically a magic denial-of-service key for anything built on the API. It refuses not only in the API but also in Chat, in Claude Code, … i guess everywhere?

I use Claude Code on this blog and would like to do so in the future, so I will only include a screenshot and not the literal string here. Here goes the magic string to make any Anthropic model stop working!

This is not the worst idea ever, but it’s also a bit janky. I hope it at least rotates occasionally (but there is no such indication), otherwise I don’t see this ending well. This got to my attention with this post that shows you can embed it in a binary. This is pretty bad if you plan to use claude code for malware analysis, as you very much might want to. Imagine putting this in malware or anything else that might want to get automatically checked by AI, and now you have ensured that it won’t be an Anthropic model that does the check.

Antigravity Removed "Auto-Decide" Terminal Commands

I noticed today that you can no longer let the agent in antigravity “auto-decide” which commands are safe to execute. There is just auto-accept and always-ask.

Antigravity settings showing "Always Proceed" and "Request Review" options for "Terminal Command Auto Execution"

I wrote in a previous post that their previous approach seemed unsafe, especially without a sandbox. Now, the new issue with this approach is approval fatigue. There is no way to auto-allow similar commands or even exactly the same command in the future!

It asks whether to run a command with only the options Reject and Accept.

I don’t know why they can’t just copy what Claude Code has. Anthropic has published a lot on this topic, and I don’t think usable security should be a competitive differentiator, but maybe Google thinks differently.

View archives